# Delete a model
Source: https://docs.getpaperjet.com/api-reference/delete-apiv1adminmodelsdelete
delete /api/v1/admin/models/delete
Delete a model
# Revoke an API key
Source: https://docs.getpaperjet.com/api-reference/delete-apiv1api-keys
delete /api/v1/api-keys/{id}
Revoke an API key
# Delete a workflow
Source: https://docs.getpaperjet.com/api-reference/delete-apiv1workflows
put /api/v1/workflows/{workflowId}
Delete a workflow
# List all models
Source: https://docs.getpaperjet.com/api-reference/get-apiv1adminmodels
get /api/v1/admin/models
List all models
# Get runtime configuration
Source: https://docs.getpaperjet.com/api-reference/get-apiv1adminruntime-config
get /api/v1/admin/runtime-config
Returns the models that are used in workflow execution
# Get all API keys
Source: https://docs.getpaperjet.com/api-reference/get-apiv1api-keys
get /api/v1/api-keys
Get all API keys for the organization
# Get all workflow executions
Source: https://docs.getpaperjet.com/api-reference/get-apiv1executions
get /api/v1/executions
Get all workflow executions for the organization
# Get execution details
Source: https://docs.getpaperjet.com/api-reference/get-apiv1executions-1
get /api/v1/executions/{executionId}
Get workflow execution details by ID
# Export execution data
Source: https://docs.getpaperjet.com/api-reference/get-apiv1executions-export
get /api/v1/executions/{executionId}/export
Export workflow execution data
# Get execution file
Source: https://docs.getpaperjet.com/api-reference/get-apiv1executions-file
get /api/v1/executions/{executionId}/file
Get presigned URL for execution file
# Get execution status
Source: https://docs.getpaperjet.com/api-reference/get-apiv1executions-status
get /api/v1/executions/{executionId}/status
Get workflow execution status by ID
# Get all workflows
Source: https://docs.getpaperjet.com/api-reference/get-apiv1workflows
get /api/v1/workflows
Get all workflows for the organization
# Get workflow details
Source: https://docs.getpaperjet.com/api-reference/get-apiv1workflows-1
get /api/v1/workflows/{workflowId}
Get workflow details by ID
# Get workflow execution details
Source: https://docs.getpaperjet.com/api-reference/get-apiv1workflows-executions
get /api/v1/workflows/{workflowId}/executions/{workflowExecutionId}
Get workflow execution details
# Add a new model
Source: https://docs.getpaperjet.com/api-reference/post-apiv1adminmodelsadd
post /api/v1/admin/models/add
Add a new model
# Validate model connection
Source: https://docs.getpaperjet.com/api-reference/post-apiv1adminmodelsvalidate-connection
post /api/v1/admin/models/validate-connection
Validate model connection
# Set runtime model configuration
Source: https://docs.getpaperjet.com/api-reference/post-apiv1adminruntime-config
post /api/v1/admin/runtime-config
Set runtime model configuration
# Create a new API key
Source: https://docs.getpaperjet.com/api-reference/post-apiv1api-keys
post /api/v1/api-keys
Create a new API key
# Create a new workflow
Source: https://docs.getpaperjet.com/api-reference/post-apiv1workflows
post /api/v1/workflows
Create a new workflow
# Execute a workflow
Source: https://docs.getpaperjet.com/api-reference/post-apiv1workflows-execute
post /api/v1/workflows/{workflowId}/execute
Execute a workflow with a file
# Update an existing model
Source: https://docs.getpaperjet.com/api-reference/put-apiv1adminmodelsupdate
put /api/v1/admin/models/update
Update an existing model
# Update a workflow
Source: https://docs.getpaperjet.com/api-reference/put-apiv1workflows
put /api/v1/workflows/{workflowId}
Update an existing workflow
# Introduction
Source: https://docs.getpaperjet.com/index
PaperJet | Privacy-first document processing
## What is PaperJet?
PaperJet is a platform for extracting structured data from documents, all while using your own infrastructure.
### Features
* Structured data extraction - define a schema and extract it from any supported document (docx, pdf, images)
* Fully open-source - The web and self-hosted versions have the same feature set
* Zero cloud dependencies - PaperJet doesn't depend on any cloud services. Everything is self-contained in Docker
* Built for large documents: easily ingest hundreds of pages at once
* Use any LLM with your own keys (BYOK)
* supports major cloud providers like OpenAI and Gemini
* local providers: VLLM, LM Studio and Ollama
### Getting started
If you're looking to start using PaperJet, head over to the [User Guide](/pages/user/workflow-basics).
If you want to see how to set it up yourself, check out the [Adminstrator Guide](/pages/admin/quickstart).
Learn how to start using PaperJet
Learn how to set up and manage your PaperJet instance
# Deployment
Source: https://docs.getpaperjet.com/pages/admin/deployment
Learn how to run and manage PaperJet
# Quickstart
Source: https://docs.getpaperjet.com/pages/admin/quickstart
Learn how to run and manage PaperJet
PaperJet can run on any environment that supports Docker.
Setting up your own PaperJet instance is a very simple process.
Deploy PaperJet onto any VPS
Create an admin user and add a model
Test it out to make sure everything works
## Hardware requirements
We recommend a minimum of 2 vCPU and 4gb of RAM.
Both x86 and ARM based systems are supported.
## Docker compose
Docker compose is the easiest way to set up PaperJet on any environment.
### One-liner setup
Run these commands to deploy PaperJet instantly:
```bash theme={null}
curl -o docker-compose.yml https://raw.githubusercontent.com/MLNativeAI/paperjet/main/apps/docs/deployment/docker-compose.yml
docker compose up -d
```
This will download the complete production setup and start all services in the background.
## Configuration
Coming soon. The docker-compose is pre-configured to just start out of the box
## Model providers
### vLLM
VLLM is the recommended platform for running AI models.
### LM Studio
Currently not supported due to [a bug with structured outputs](https://github.com/lmstudio-ai/lmstudio-bug-tracker/issues/189)
# Authoring workflows
Source: https://docs.getpaperjet.com/pages/user/creating-workflows
How to create and edit workflows
PaperJet uses LLMs in the extraction process. The size and capabilities of the LLM can vary greatly.
If you want to get good results, especially with smaller models, you must limit the amount of "work" that the LLM must perform.
This is a set of guidelines to help you get good results with your documents. We've found this to work well for both small inputs (images) as well as very large documents (500+ pages)
### Field names are important
Field names are used to match the data from the source document. This means that using descriptive, self-explaining field names is crucial for good results.
You don't have to avoid spaces in field names, but it is recommended.
Don't try to be clever.
Good example: invoice\_number
Bad example: the text from the 3rd row on the left side
### Use descriptions to clarify intent
Descriptions act as an additional layer of instructions to help match data from the source document.
You can add a description to any object, field or column to help the engine with extracting the correct data.
Good example: Full name of the individual
Occasionally, the data you would like to extract can have different names/labels on the source documents.
This is a good use case for descriptions to handle - list out the names under which a field can appear in a source document
Field name: "Tax ID"
Description: "Can also appear as VAT ID or EIN
number"
### Use descriptions for data manipulation and filtering
You can also use the description to perform filtering and/or data manipulations, such as "Format the date in YYYY-MM-DD" or "Skip rows containing X"
Don't overuse data manipulations, especially with smaller models{" "}
If possible, it's best to do filtering in postprocessing, outside of PaperJet.
See the next page for some examples.
# Executions
Source: https://docs.getpaperjet.com/pages/user/executions
How to run and export data from workflows
Executions represent a single document processing pipeline. When you upload a document to a workflow, you spawn a new execution.
To create an execution, you can either click "Execute" on the Workflows page and submit a new document, or do it via the API endpoint.
## Process
When you create a new execution, it's initially in the "Queued" state. Once it's picked up by the worker, it will shortly resolve to the "Completed", upon which you can view and export the results.
## Details page
All successfully executions can be inspected by going to the details page.
You can toggle between viewing just the results, or the results side-by-side with the original document.
## Exporting
You can export the data either as a .csv or a json file from the UI. You can also access the results via the API.
# Workflow basics
Source: https://docs.getpaperjet.com/pages/user/workflow-basics
Data types and configuration
Workflows are the core of PaperJet. A workflow is a blueprint that describes the configuration and the data structure that should be extracted from a document.
Workflow instances are called Executions.
## Creating a workflow
You can start either with a pre-built template or create your own data structure from scratch. You can also create a new workflow via the API.
When you create an empty workflow, you'll be greeted with an empty configuration. You need to describe the shape of the data that should be extracted from your documents.
 ## Data types
A workflow configuration must have one or more objects to be extracted.
### Object
Object are the "root" nodes of a configuration. Each object can have multiple fields and/or tables.
You must have at least one object defined in your configuration.
You should treat objects like semantical groups for your data.
### Field
A field is a singular data variable that will be populated during extraction. There are 3-built in types:
* Text
* Number
* Date
### Table
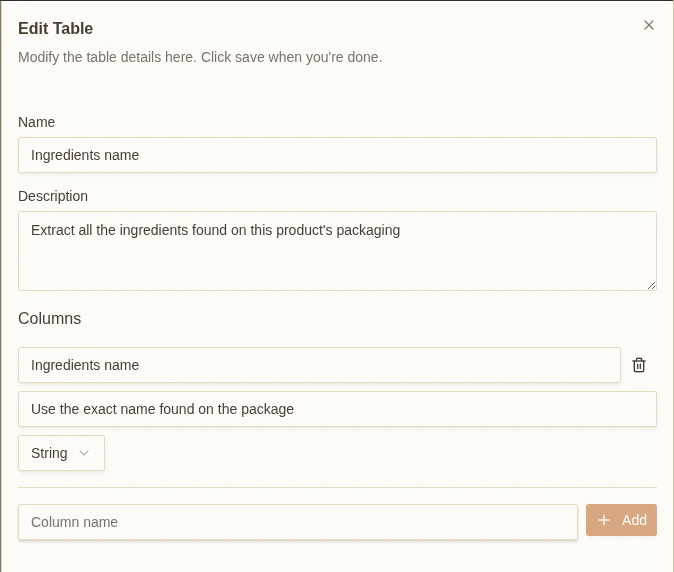
Tables are used to extract repetitive data such as lists or tables. Each table must have one or more columns, where each column definition is a Field
Here's an example of a list that extracts ingredients from a product photograph:
 ## Runtime configuration
For every workflow, you must select one of two execution modes:
### Accurate mode
This is the default extraction mode, which uses LLMs to extract the data from each document page. It's recommended for the most accurate result. It leverages the visual capabilities of the LLM to perform the initial data extraction.
### Fast mode
The fast mode uses native OCR for the initial data extraction before passing the data to the LLM to extract the configuration. It works very well for high-quality documents, such as native PDFs or docx files, but it likely won't work for scans or image inputs.
See the next page to learn how to create effective workflows.
# Workflow examples
Source: https://docs.getpaperjet.com/pages/user/workflow-examples
Learn how to create your own workflows based on these samples
Internally, all workflows are stored as a JSON object. Here are some sample workflow configurations from our templates.
You can use these as reference on how to structure your own workflows. This schema is also what our API expects when creating a workflow.
## Invoice
```JSON theme={null}
{
"objects": [
{
"name": "Invoice Header",
"fields": [
{
"name": "Invoice Number",
"description": "Unique invoice identifier",
"type": "string"
},
{
"name": "Invoice Date",
"description": "Date the invoice was issued",
"type": "string"
},
{
"name": "Due Date",
"description": "Payment due date",
"type": "string"
},
{
"name": "Vendor Name",
"description": "Name of the vendor or seller",
"type": "string"
},
{
"name": "Vendor Address",
"description": "Address of the vendor",
"type": "string"
},
{
"name": "Customer Name",
"description": "Name of the customer or buyer",
"type": "string"
},
{
"name": "Customer Address",
"description": "Address of the customer",
"type": "string"
},
{
"name": "Invoice Currency",
"type": "string",
"description": "3-letter currency code"
}
]
},
{
"name": "Line Items",
"tables": [
{
"name": "Invoice Line Items",
"columns": [
{
"name": "Description",
"type": "string"
},
{
"name": "Quantity",
"type": "number"
},
{
"name": "Unit Price",
"type": "number"
},
{
"name": "Total",
"type": "number"
}
]
}
]
},
{
"name": "Invoice Totals",
"fields": [
{
"name": "Subtotal",
"description": "Total before taxes",
"type": "number"
},
{
"name": "Tax Amount",
"description": "Total tax amount",
"type": "number"
},
{
"name": "Total Amount",
"description": "Final total amount due",
"type": "number"
}
]
}
]
}
```
## Bank statement
```JSON theme={null}
{
"objects": [
{
"name": "Account Information",
"fields": [
{
"name": "Account Holder Name",
"description": "Name of the account holder",
"type": "string"
},
{
"name": "Account Number",
"description": "Bank account number",
"type": "string"
},
{
"name": "Bank Name",
"description": "Name of the bank",
"type": "string"
},
{
"name": "Statement Period",
"description": "Period covered by the statement",
"type": "string"
},
{
"name": "Opening Balance",
"description": "Balance at the start of the period",
"type": "number"
},
{
"name": "Closing Balance",
"description": "Balance at the end of the period",
"type": "number"
}
]
},
{
"name": "Transactions",
"tables": [
{
"name": "Transaction History",
"columns": [
{
"name": "Date",
"type": "string"
},
{
"name": "Description",
"type": "string"
},
{
"name": "Amount",
"type": "number"
},
{
"name": "Balance",
"type": "number"
}
]
}
]
}
]
}
```